We Tested AI Assistants Across 7 Personal Tasks. Here's What We Found

By Team Besthunt
There are a lot of articles on the internet telling you which AI assistant is the best. But they almost always land on the same answer: ChatGPT, Claude, or Gemini. The general-purpose ones.
We wanted to look somewhere else.
Instead of looking at tools that do everything, we looked at tools built specifically for personal, day-to-day tasks.
We started by independently testing how some of these assistants actually perform on everyday tasks. Then we compared what we found with product documentation, industry benchmarks, and how other experts had tested and reviewed the same tools.
Here's what we found.
Which AI assistants are actually being tested?
After looking at the available testing and evidence, these 11 assistants make up our core comparison.
Assistant | Company | Underlying model | What it does |
|---|---|---|---|
Instinct | Spear Street Technology | Uses a proprietary Instinct mode | Text-and-call personal assistant that can research, communicate, book, purchase, and complete tasks across connected services |
Pally | Pally, Inc. | Anthropic, OpenAI models as well as open-source models like Kimi K3 and GLM 5.2. | Text-based assistant that can research, remember, communicate, and take action across connected apps |
Ollie | Ollie AI | Anthropic, Google, and OpenAI models via commercial APIs | Personal assistant for household tasks, email, calendars, reminders, research, and everyday planning |
Shuffle | Shuffle | Multiple models | Text-and-call assistant for images, games, recommendations, and everyday tasks |
Tomo | Tomo | Model-agnostic; supports multiple model options | Goal and accountability assistant for planning, follow-through, and everyday tasks |
Poke | Interaction Company | Multi-model | Proactive assistant that works through messaging and can take actions across connected services |
szn | theszn.ai | Multiple models | Personal agent with its own number, inbox, and computer |
Caddy | Caddy | Anthropic | Personal assistant for reservations, errands, travel, shopping, calendar updates, and other everyday tasks |
Muse | Meta | Muse Spark family | Personal AI agent for email, shopping, travel, forms, and other multi-step tasks |
Asmi | Asmi AI | Google Gemini | Voice-based assistant that makes calls, navigates IVR, books appointments, and handles real-world chores |
Wajo | Wajo | Multiple models | Action agent that can email, call, book, buy, coordinate, and operate through connected services |
Most of these assistants don't depend on a single underlying model. Instead, many use multiple models or are designed to be model-agnostic, allowing the product to choose different models for different jobs.
What increasingly separates these products is what surrounds the model: memory, integrations, access to the web, proactive behavior, and the ability to take action outside the conversation.
The products are also at very different stages. Some are established paid products, while others remain in beta, preview, or limited release. For example, Muse is particularly new, so there is less independent real-world testing available for it.
What characteristics are we testing?
We looked at eight characteristics that matter when you're actually handing an assistant part of your life.
A number means the capability was available and could be evaluated.
— means we couldn't reliably verify or evaluate a user-facing version of that capability. It does not mean the underlying AI model is technically incapable of it.
Assistant | Memory | Web | Multi-step | Proactive | Access | Personalization | Text | Image |
|---|---|---|---|---|---|---|---|---|
Instinct | 8 | 7 | 8 | 7 | 6.5 | 8 | 8 | — |
Pally | 7 | 7 | 8 | 7 | 7.5 | 7 | 8 | 8 |
Ollie | 7 | 8 | 7.5 | 7 | 7.5 | 7 | 7 | — |
Shuffle | 6 | 7 | 7 | 6 | 7 | 6 | 7 | 8 |
Tomo | 6 | 7 | 7 | 7 | 7 | 6 | 7 | — |
Poke | 7 | 3 | 7 | 7 | 7 | 7 | 7 | — |
szn | 8 | 7 | 7 | 6 | 7 | 8 | 7 | — |
Caddy | 8 | 7 | 7 | 6 | 7 | 8 | 7 | — |
Muse* | 7 | 7 | 7 | 6 | 7 | 7 | 7 | 7 |
Asmi | 6 | — | 7 | 5 | — | 6 | 7 | — |
Wajo / Fo | 7 | 2 | 7 | 7 | 6.5 | 7 | 6 | — |
Boba | — | 6 | 6 | — | — | — | 7 | 7 |
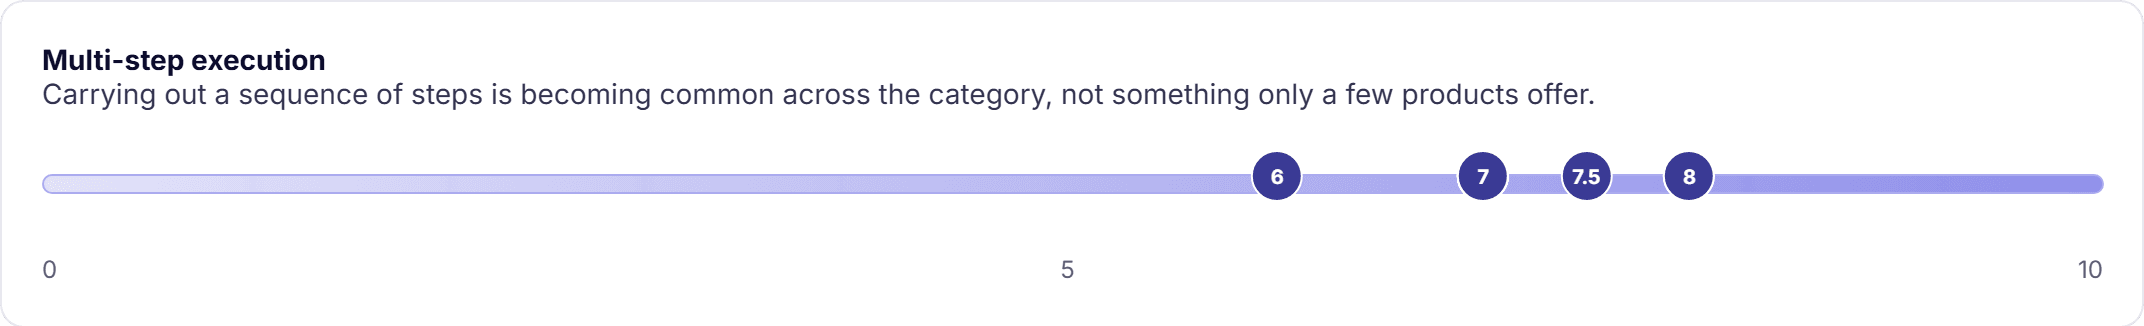
Multi-step execution is one of the most consistent characteristics in the data. Scores sit between 6 and 8, with most assistants clustered around 7. That suggests carrying out a sequence of steps is becoming a common part of the personal-assistant category rather than something offered by only a few products.
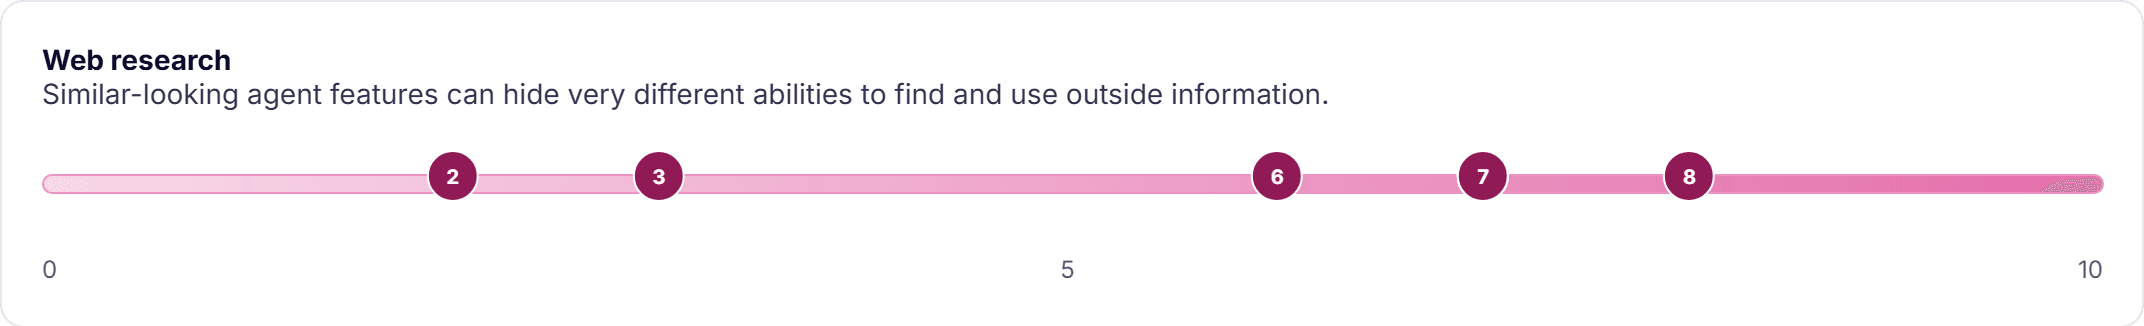
Web research is much more uneven. Among the assistants where it could be evaluated, scores range from 2 to 8. That indicates research remains a major point of differentiation. Products may offer similar-looking agent features, but their ability to independently find and work with outside information can be very different.
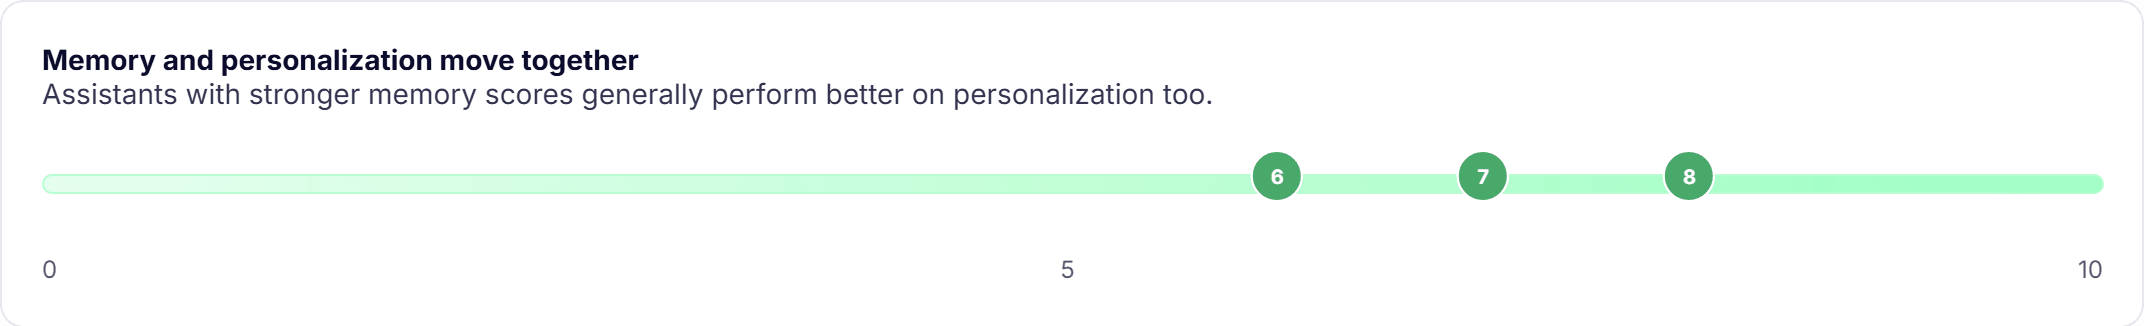
Memory and personalization also tend to move together. Assistants with stronger memory scores generally perform better on personalization. That points to a broader product pattern: remembering context is becoming part of how these assistants adapt to individual users, rather than memory existing as a standalone feature.
How does each AI assistant perform across personal tasks?
We tested the assistants across seven everyday scenarios:
Task | Instinct | Muse | Pally | Ollie | Tomo | Shuffle | Caddy | szn | Poke | Asmi | Wajo / Fo |
|---|---|---|---|---|---|---|---|---|---|---|---|
Research | 8 | 7 | 7 | 8 | 7 | 7 | 7.5 | 7 | 3 | 6 | 2 |
Writing | 8 | 7 | 7 | 7 | 7 | 7 | 7 | 7 | 7 | 7 | 6 |
Organizing | 7 | 7 | 8 | 7 | 7 | 7 | 7 | 7 | 7 | 7 | 7 |
Design | 6 | 7 | 8 | 8 | 8 | 8 | 7 | 7 | 6 | 8 | 6 |
Booking | 8 | 7 | 7.5 | 7.5 | 7.5 | 7.5 | 7.5 | 7.5 | 3 | 5.5 | 4.5 |
Travel | 8 | 7 | 7 | 7 | 8 | 8 | 7 | 7 | 5 | 5 | 7 |
Shopping | 8 | 7 | 7 | 7 | 7 | 7 | 7 | 7 | 5 | 5 | 5 |
Writing is one of the most consistent tasks across the market. It averages just over 7, with every assistant scoring between 6 and 8. This pattern makes sense given that strong text generation is already common across major AI models, so assistants built on different model stacks still end up performing fairly similarly at writing.
Research is where the differences become much bigger. Scores range from 2 to 8, the widest gap among the tasks we tested. This suggests research depends on more than the underlying model. How an assistant searches the web, finds sources, and brings external information into a task can create much bigger differences between products.
Booking shows a similar gap when assistants have to take action. Scores range from 3 to 8, compared with the much tighter range for writing. Many assistants can understand what someone wants to book or recommend an option, but carrying that request through depends on browser access, integrations, approvals, and the ability to interact reliably with external services.
The bottom line
No single assistant performs equally well across every category. Writing and multi-step execution are two of the most consistent areas across the products we tested. The bigger differences appear in web research and booking. These tasks require assistants to go beyond the conversation, find outside information, or interact with other services.
Therefore, the right assistant depends on what you want it to do. If you mainly need help writing, organizing information, or planning, the differences between many of these products are fairly small. If you need an assistant to research independently or complete a booking, the differences become much larger. In those cases, it is more useful to look at the individual research and booking scores than the overall average.
FAQs
Why weren't ChatGPT, Claude, or Gemini included?+
ChatGPT, Claude, and Gemini are general-purpose assistants designed to handle a wide range of requests. This comparison focuses on products built around personal, everyday tasks such as booking, research, planning, travel, and errands.
What does it mean when a score is provisional, like Muse's?+
It means there is less independent, real-world testing available for the product. We scored Muse based on what we could evaluate, but the scores may change as more testing becomes available.
Should I be concerned about giving these assistants access to my email, calendar, or payment methods?+
Before connecting sensitive accounts, check each product's privacy policy, permissions, and data-handling practices. Assistants that book, buy, manage calendars, or work with email may need access to personal accounts and data.